在 Cursor 中进行机器学习:TensorFlow.js、ONNX 与 AI 辅助的 ML 流水线
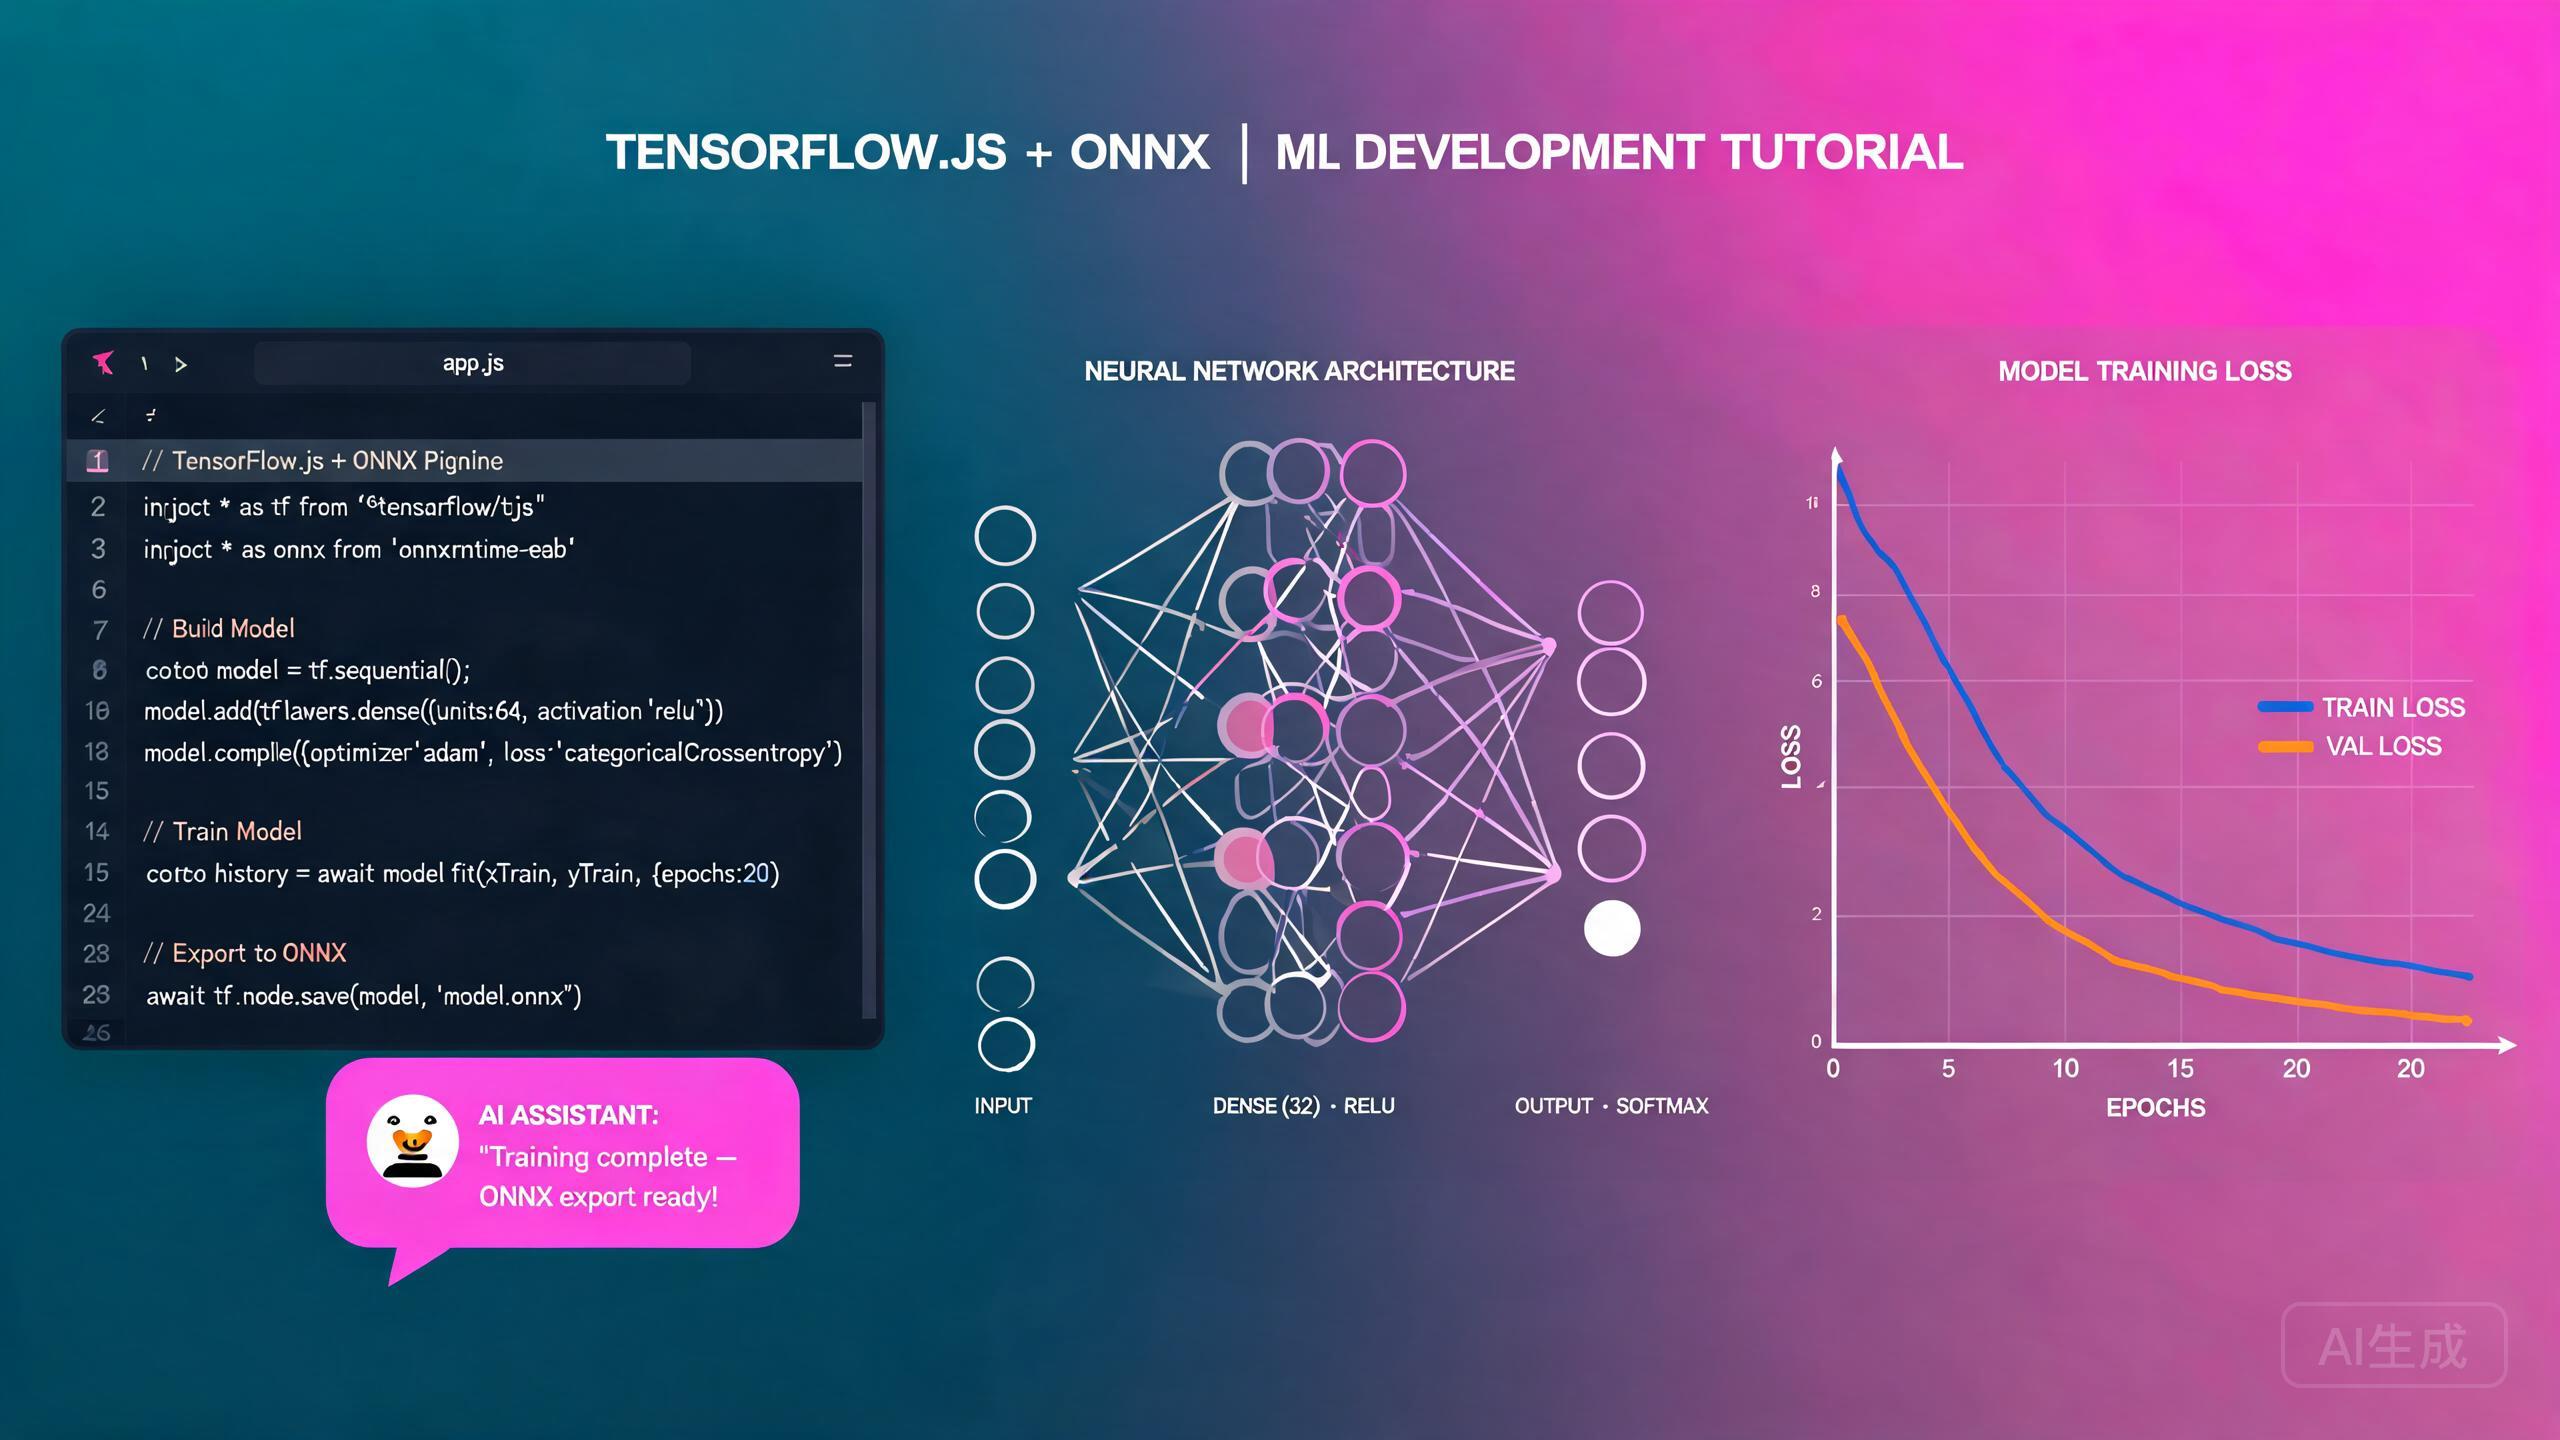
机器学习为应用带来预测智能,从图像分类到自然语言处理和推荐系统。Cursor 是一款 AI 驱动的 IDE 编辑器,加速 ML 工作流的每个阶段:数据预处理、模型设计、训练循环、评估指标和部署。本指南涵盖用于浏览器端推理和训练的 TensorFlow.js、用于跨平台模型执行的 ONNX Runtime、数据预处理流水线、模型评估策略,以及将自然语言描述转化为可运行训练脚本的 AI 辅助 ML 流水线生成。
前提条件
在开始之前,请确保你具备以下条件:
- Cursor(建议使用最新版本)作为你的 IDE 编辑器
- Node.js 18 或更高版本
- 对 JavaScript、TypeScript 和 Python 有基本了解
- 对神经网络、损失函数和梯度下降有概念性理解
如果你刚接触机器学习,在编写任何代码之前,请让 Cursor 解释监督学习、无监督学习和强化学习之间的区别。理解你的问题属于哪种范式决定了你的整个方法:数据标注、模型架构和评估指标。
理解 Cursor 中的 ML 工作流
一个典型的机器学习项目遵循可预测的流水线。Cursor 帮助你实现和连接每个阶段:
- 数据收集和预处理:清理原始数据,处理缺失值,标准化特征,并拆分为训练/验证/测试集。
- 模型设计:选择架构(密集网络、CNN、RNN、Transformer)并定义层。
- 训练:使用选定的优化器和损失函数运行训练循环,监控指标,并应用早停。
- 评估:用精确率、召回率、F1 分数、混淆矩阵等指标衡量性能。
- 部署:导出模型,如需要则转换为 ONNX 格式,并在浏览器或服务器上运行推理。
项目脚手架
让 Cursor 搭建一个 TensorFlow.js 项目:
Create a TypeScript project for machine learning with TensorFlow.js.
Set up Vite for the frontend, install @tensorflow/tfjs and
@tensorflow/tfjs-node, and create a folder structure for data,
models, training scripts, and evaluation utilities.
Cursor 生成:
my-ml-project/
  data/
    raw/
    processed/
  models/
  src/
    train.ts
    evaluate.ts
    predict.ts
  src-tauri/ (optional, for desktop deployment)
  package.json
  tsconfig.json
训练时始终使用 @tensorflow/tfjs-node(绑定到原生 C++ TensorFlow 库),而不是纯 @tensorflow/tfjs(在浏览器中通过 WebGL/WASM 运行)。在 Node.js 上训练比基于浏览器的训练快 10 到 50 倍,因为它利用了 SIMD 指令和原生内存管理。浏览器 TF.js 用于推理,而非重度训练。
数据预处理
数据预处理消耗 ML 开发的大部分时间。Cursor 可以生成完整的预处理流水线,处理清理、标准化、编码和拆分。
预处理流水线
// src/preprocessing.ts
import * as tf from '@tensorflow/tfjs-node';

export interface DatasetStats {
  mean: number[];
  std: number[];
  min: number[];
  max: number[];
}

export class DataPreprocessor {
  private stats: DatasetStats | null = null;

  /**
   * Compute normalization statistics from training data.
   * Must be called before normalize() and applied identically
   * to training, validation, and test sets.
   */
  computeStats(data: number[][]): void {
    const tensor = tf.tensor2d(data);
    const mean = tensor.mean(0).dataSync();
    const std = tensor.sub(tensor.mean(0)).square().mean(0).sqrt().dataSync();
    const min = tensor.min(0).dataSync();
    const max = tensor.max(0).dataSync();

    this.stats = {
      mean: Array.from(mean),
      std: Array.from(std).map((s, i) => (s < 1e-8 ? 1 : s)), // Avoid division by zero
      min: Array.from(min),
      max: Array.from(max),
    };

    tensor.dispose();
  }

  /**
   * Apply Z-score normalization: (x - mean) / std
   */
  normalize(data: number[][]): number[][] {
    if (!this.stats) throw new Error('Call computeStats() first');
    return data.map((row) =>
      row.map((val, i) => (val - this.stats!.mean[i]) / this.stats!.std[i])
    );
  }

  /**
   * One-hot encode categorical labels
   */
  encodeLabels(labels: number[], numClasses: number): number[][] {
    return labels.map((label) => {
      const encoded = new Array(numClasses).fill(0);
      encoded[label] = 1;
      return encoded;
    });
  }

  /**
   * Split data into train, validation, and test sets
   */
  split(
    data: number[][],
    labels: number[][],
    trainRatio = 0.7,
    valRatio = 0.15
  ): { trainX: number[][]; trainY: number[]; valX: number[][]; valY: number[]; testX: number[][]; testY: number[] } {
    const n = data.length;
    const indices = Array.from({ length: n }, (_, i) => i);
    // Fisher-Yates shuffle
    for (let i = n - 1; i > 0; i--) {
      const j = Math.floor(Math.random() * (i + 1));
      [indices[i], indices[j]] = [indices[j], indices[i]];
    }
    const trainEnd = Math.floor(n * trainRatio);
    const valEnd = trainEnd + Math.floor(n * valRatio);
    const pick = (idx: number[]) => ({ x: idx.map((i) => data[i]), y: idx.map((i) => labels[i]) });
    const train = pick(indices.slice(0, trainEnd));
    const val = pick(indices.slice(trainEnd, valEnd));
    const test = pick(indices.slice(valEnd));
    return { trainX: train.x, trainY: train.y, valX: val.x, valY: val.y, testX: test.x, testY: test.y };
  }

  /**
   * Handle missing values by imputing the column mean
   */
  imputeMissing(data: (number | null)[][]): number[][] {
    const numCols = data[0].length;
    const colSums = new Array(numCols).fill(0);
    const colCounts = new Array(numCols).fill(0);

    data.forEach((row) => {
      row.forEach((val, col) => {
        if (val !== null && !isNaN(val)) { colSums[col] += val; colCounts[col]++; }
      });
    });

    const colMeans = colSums.map((sum, i) => (colCounts[i] > 0 ? sum / colCounts[i] : 0));

    return data.map((row) => row.map((val, col) => (val === null || isNaN(val) ? colMeans[col] : val)));
  }

  getStats(): DatasetStats | null {
    return this.stats;
  }
}
让 Cursor 生成合成数据集来测试你的预处理流水线。类似"生成一个包含 1000 行、8 个数值特征、2 个分类列和 5% 缺失值的合成 CSV"的提示可以在不需要先查找和下载真实数据集的情况下为你提供真实的测试数据。
模型设计与训练
TensorFlow.js 使用分层 API 来构建神经网络。Cursor 根据你的问题描述生成完整的模型架构。
构建分类模型
// src/models/classifier.ts
import * as tf from '@tensorflow/tfjs-node';

export interface ModelConfig {
  inputSize: number;
  numClasses: number;
  hiddenLayers: number[];
  learningRate: number;
  dropoutRate: number;
}

export function buildClassifier(config: ModelConfig): tf.LayersModel {
  const model = tf.sequential();

  // Input layer
  model.add(
    tf.layers.dense({
      inputShape: [config.inputSize],
      units: config.hiddenLayers[0],
      activation: 'relu',
      kernelInitializer: 'heNormal',
    })
  );

  model.add(tf.layers.batchNormalization());
  model.add(tf.layers.dropout({ rate: config.dropoutRate }));

  // Hidden layers
  for (let i = 1; i < config.hiddenLayers.length; i++) {
    model.add(
      tf.layers.dense({
        units: config.hiddenLayers[i],
        activation: 'relu',
        kernelInitializer: 'heNormal',
      })
    );
    model.add(tf.layers.batchNormalization());
    model.add(tf.layers.dropout({ rate: config.dropoutRate }));
  }

  // Output layer
  model.add(
    tf.layers.dense({
      units: config.numClasses,
      activation: 'softmax',
    })
  );

  model.compile({
    optimizer: tf.train.adam(config.learningRate),
    loss: 'categoricalCrossentropy',
    metrics: ['accuracy'],
  });

  return model;
}
带回调的训练循环
// src/train.ts
import * as tf from '@tensorflow/tfjs-node';
import { buildClassifier, ModelConfig } from './models/classifier';
import { DataPreprocessor } from './preprocessing';
import * as fs from 'fs/promises';
import * as path from 'path';

interface TrainingResult {
  finalAccuracy: number;
  finalLoss: number;
  epochsRun: number;
  modelPath: string;
}

export async function trainModel(
  dataPath: string,
  config: ModelConfig,
  outputDir: string
): Promise<TrainingResult> {
  // Load and preprocess data
  const rawData = await loadCSV(dataPath);
  const features = rawData.map((row) => row.slice(0, config.inputSize));
  const labels = rawData.map((row) => row[config.inputSize]);

  const preprocessor = new DataPreprocessor();
  preprocessor.computeStats(features);
  const normalizedFeatures = preprocessor.normalize(features);

  const encodedLabels = preprocessor.encodeLabels(labels, config.numClasses);

  const split = preprocessor.split(normalizedFeatures, labels);

  const trainXTensor = tf.tensor2d(split.trainX);
  const trainYTensor = tf.tensor2d(
    preprocessor.encodeLabels(split.trainY, config.numClasses)
  );
  const valXTensor = tf.tensor2d(split.valX);
  const valYTensor = tf.tensor2d(
    preprocessor.encodeLabels(split.valY, config.numClasses)
  );

  // Build model
  const model = buildClassifier(config);

  // Train with callbacks
  const history = await model.fit(trainXTensor, trainYTensor, {
    epochs: 100,
    batchSize: 32,
    validationData: [valXTensor, valYTensor],
    shuffle: true,
    callbacks: [
      tf.callbacks.earlyStopping({ monitor: 'val_loss', patience: 10, minDelta: 0.001, restoreBestWeight: true }),
      {
        onEpochEnd: async (epoch, logs) => {
          if (epoch > 0 && epoch % 20 === 0) {
            console.log(`Epoch ${epoch}: Consider reducing learning rate`);
          }
          console.log(`Epoch ${epoch + 1}: loss=${logs?.loss?.toFixed(4)}, acc=${logs?.acc?.toFixed(4)}, val_loss=${logs?.val_loss?.toFixed(4)}, val_acc=${logs?.val_acc?.toFixed(4)}`);
        },
      },
    ],
  });

  // Save model and preprocessor stats
  const modelPath = path.join(outputDir, 'model');
  await model.save(`file://${modelPath}`);
  await fs.writeFile(path.join(outputDir, 'preprocessor-stats.json'), JSON.stringify(preprocessor.getStats(), null, 2));

  // Cleanup tensors
  [trainXTensor, trainYTensor, valXTensor, valYTensor].forEach((t) => t.dispose());

  const lastEpoch = history.epoch.length;
  const finalAccuracy = history.history.val_acc?.[lastEpoch - 1] ?? 0;
  const finalLoss = history.history.val_loss?.[lastEpoch - 1] ?? 0;

  console.log(`\nTraining complete after ${lastEpoch} epochs`);
  console.log(`Best validation accuracy: ${finalAccuracy.toFixed(4)}`);
  console.log(`Model saved to: ${modelPath}`);

  return { finalAccuracy, finalLoss, epochsRun: lastEpoch, modelPath };
}

async function loadCSV(filePath: string): Promise<number[][]> {
  const lines = (await fs.readFile(filePath, 'utf-8')).trim().split('\n');
  const header = lines[0].split(',').length;
  return lines.slice(1)
    .map((line) => line.split(',').map((v) => parseFloat(v.trim())))
    .filter((row) => row.length === header && row.every((v) => !isNaN(v)));
}
当训练时间过长时,让 Cursor 分析瓶颈。类似"分析我的训练脚本中的性能问题。检查张量内存泄漏、不必要的同步操作和数据加载瓶颈"的提示可以识别未释放的张量导致内存压力和减速等问题。
TensorFlow.js 张量不会被垃圾回收。你创建的每个张量都会保留在内存中,直到你调用 .dispose() 或用 tf.tidy() 包装。在训练循环中,不释放张量会导致内存不断增长直到进程崩溃。始终在使用后释放张量,并对短期计算使用 tf.tidy()。
模型评估
评估不仅仅是准确率。Cursor 生成全面的评估代码,计算多个指标并可视化结果。
评估指标
// src/evaluate.ts
import * as tf from '@tensorflow/tfjs-node';
import { DataPreprocessor } from './preprocessing';

export interface EvaluationResult {
  accuracy: number;
  precision: number;
  recall: number;
  f1Score: number;
  confusionMatrix: number[][];
  perClassMetrics: Array<{
    class: number;
    precision: number;
    recall: number;
    f1: number;
    support: number;
  }>;
}

export async function evaluateModel(
  model: tf.LayersModel,
  testX: number[][],
  testY: number[],
  numClasses: number,
  preprocessor: DataPreprocessor
): Promise<EvaluationResult> {
  const inputTensor = tf.tensor2d(preprocessor.normalize(testX));
  const predictions = model.predict(inputTensor) as tf.Tensor;
  const predicted = predictions.argMax(1).dataSync();
  const actual = tf.tensor1d(testY).dataSync();

  // Build confusion matrix
  const confusionMatrix: number[][] = Array.from({ length: numClasses }, () => new Array(numClasses).fill(0));
  for (let i = 0; i < predicted.length; i++) confusionMatrix[actual[i]][predicted[i]]++;

  // Per-class metrics
  const perClassMetrics: EvaluationResult['perClassMetrics'] = [];
  let totalCorrect = 0;
  let totalSamples = 0;

  for (let c = 0; c < numClasses; c++) {
    const tp = confusionMatrix[c][c];
    const fp = confusionMatrix.reduce((sum, row, idx) => sum + (idx !== c ? row[c] : 0), 0);
    const fn = confusionMatrix[c].reduce((sum, val, idx) => sum + (idx !== c ? val : 0), 0);
    const support = confusionMatrix[c].reduce((a, b) => a + b, 0);

    const precision = tp + fp > 0 ? tp / (tp + fp) : 0;
    const recall = tp + fn > 0 ? tp / (tp + fn) : 0;
    const f1 = precision + recall > 0 ? (2 * precision * recall) / (precision + recall) : 0;

    perClassMetrics.push({ class: c, precision, recall, f1, support });
    totalCorrect += tp;
    totalSamples += support;
  }

  // Macro-averaged metrics
  const macroPrecision = perClassMetrics.reduce((sum, m) => sum + m.precision, 0) / numClasses;
  const macroRecall = perClassMetrics.reduce((sum, m) => sum + m.recall, 0) / numClasses;
  const macroF1 = perClassMetrics.reduce((sum, m) => sum + m.f1, 0) / numClasses;

  inputTensor.dispose();
  predictions.dispose();

  return {
    accuracy: totalCorrect / totalSamples,
    precision: macroPrecision,
    recall: macroRecall,
    f1Score: macroF1,
    confusionMatrix,
    perClassMetrics,
  };
}

export function printEvaluation(result: EvaluationResult): void {
  console.log('\n=== Model Evaluation ===\n');
  console.log(`Accuracy: ${(result.accuracy * 100).toFixed(2)}%`);
  console.log(`Precision: ${(result.precision * 100).toFixed(2)}%`);
  console.log(`Recall:    ${(result.recall * 100).toFixed(2)}%`);
  console.log(`F1-Score:  ${(result.f1Score * 100).toFixed(2)}%`);

  console.log('\nPer-Class Metrics:');
  console.log('Class | Precision | Recall | F1    | Support');
  result.perClassMetrics.forEach((m) => {
    console.log(`  ${m.class}   |  ${(m.precision * 100).toFixed(1)}%   | ${(m.recall * 100).toFixed(1)}%  | ${(m.f1 * 100).toFixed(1)}% | ${m.support}`);
  });

  console.log('\nConfusion Matrix:');
  result.confusionMatrix.forEach((row, i) => {
    console.log(`  ${i}: ` + row.join('  '));
  });
}
让 Cursor 生成一个基于文本的混淆矩阵可视化器和一份 HTML 报告。类似"创建一个 HTML 模板,将评估结果渲染为带样式的报告,包含混淆矩阵热力图、各类指标柱状图和汇总表"的提示可以为你提供可分享给利益相关者的评估报告。
用于跨平台推理的 ONNX Runtime
ONNX(开放神经网络交换)是一种表示 ML 模型的标准格式,可在多种平台上运行。将你的 TensorFlow.js 模型转换为 ONNX,并在浏览器、移动设备或边缘设备上运行推理。
转换为 ONNX
# scripts/convert_to_onnx.py
# Run this script to convert a saved TF model to ONNX format
import tensorflow as tf
import tf2onnx
import onnxruntime as ort
import numpy as np

# Load the saved TensorFlow model
model = tf.keras.models.load_model('models/saved_model')

# Convert to ONNX
spec = (tf.TensorSpec((None, 8), tf.float32, name='input'),)
onnx_model, _ = tf2onnx.convert.from_keras(model, input_signature=spec, opset=15)

# Save the ONNX model
with open('models/model.onnx', 'wb') as f:
    f.write(onnx_model.SerializeToString())

# Verify with ONNX Runtime
session = ort.InferenceSession('models/model.onnx')
print(f"ONNX model inputs: {session.get_inputs()[0].name}")
print(f"ONNX model outputs: {[o.name for o in session.get_outputs()]}")

# Quick sanity check with dummy data
dummy_input = np.random.randn(1, 8).astype(np.float32)
result = session.run(None, {'input': dummy_input})
print(f"Test inference output shape: {result[0].shape}")
在浏览器中运行 ONNX 推理
// src/predict.ts
import * as ort from 'onnxruntime-web';

export interface PredictionResult {
  predictedClass: number;
  confidence: number;
  probabilities: number[];
}

export class OnnxPredictor {
  private session: ort.InferenceSession | null = null;
  private inputName: string = '';
  private outputName: string = '';

  async loadModel(modelPath: string): Promise<void> {
    this.session = await ort.InferenceSession.create(modelPath, {
      executionProviders: ['wasm'],
      graphOptimizationLevel: 'all',
    });

    this.inputName = this.session.inputNames[0];
    this.outputName = this.session.outputNames[0];
  }

  async predict(features: number[], mean: number[], std: number[]): Promise<PredictionResult> {
    if (!this.session) throw new Error('Model not loaded. Call loadModel() first.');

    // Normalize input
    const normalized = features.map((val, i) => (val - mean[i]) / std[i]);

    // Create ONNX tensor
    const input = new ort.Tensor('float32', Float32Array.from(normalized), [1, normalized.length]);

    // Run inference
    const outputs = await this.session.run({ [this.inputName]: input });
    const output = outputs[this.outputName];

    // Convert to probabilities
    const probabilities = Array.from(output.data as Float32Array);
    const maxIndex = probabilities.indexOf(Math.max(...probabilities));

    return {
      predictedClass: maxIndex,
      confidence: probabilities[maxIndex],
      probabilities,
    };
  }
}
在浏览器中加载 ONNX 模型时,使用带有 wasm 执行提供程序的 onnxruntime-web。webgl 提供程序更快但与某些模型架构存在兼容性问题。让 Cursor 在你的特定模型上基准测试两种提供程序并推荐最佳方案。
ONNX 模型文件可能很大(10MB 到 500MB)。在浏览器中加载它们会阻塞 UI 线程。始终使用 Web Worker 进行 ONNX 推理以保持应用响应。让 Cursor 将预测器封装在带有消息传递 API 的 Worker 中。
AI 辅助的 ML 流水线生成
Cursor 最强大的 ML 功能是从自然语言描述中生成整个训练流水线。描述你的问题,Cursor 会生成完整的代码栈。
生成完整的流水线
Create a complete machine learning pipeline for customer churn prediction:
1. Load a CSV with columns: tenure, monthlyCharges, totalCharges, contractType, internetService, churn
2. Handle missing values in totalCharges (impute median)
3. One-hot encode contractType and internetService
4. Normalize all numeric features with Z-score
5. Split 70/15/15 train/val/test
6. Build a dense neural network with 3 hidden layers (64, 32, 16) and dropout
7. Train with Adam optimizer, binary crossentropy loss, early stopping
8. Evaluate with accuracy, precision, recall, F1, and confusion matrix
9. Save the model and preprocessor stats
10. Export to ONNX format

Write all code in TypeScript using @tensorflow/tfjs-node.
Cursor 会在多个文件中生成完整的流水线,已连接并准备好运行。这相当于手动编写 500 多行样板代码。
通过让 Cursor 修改特定部分来迭代你的流水线。例如:"将模型架构改为在每个 Dense 层之前使用 BatchNorm"或"添加类别权重平衡,因为流失类别仅占数据的 20%。" 这种增量方法让你可以快速实验而无需重写整个流水线。
模型部署模式
ONNX 模型文件可能很大(10MB 到 500MB)。在浏览器中加载它们会阻塞 UI 线程。始终使用 Web Worker 进行推理以保持应用响应。
使用 Web Worker 进行浏览器推理
// src/worker/inference-worker.ts
import { OnnxPredictor } from '../lib/predict';

let predictor: OnnxPredictor | null = null;

self.onmessage = async (event: MessageEvent) => {
  const { type, modelPath, features, stats } = event.data;
  if (type === 'load' && modelPath) {
    predictor = new OnnxPredictor();
    await predictor.loadModel(modelPath);
    self.postMessage({ type: 'loaded' });
  } else if (type === 'predict' && features && stats && predictor) {
    const result = await predictor.predict(features, stats.mean, stats.std);
    self.postMessage({ type: 'result', result });
  }
};
在主线程中使用 Worker
// src/lib/inference-client.ts
import { PredictionResult } from './predict';

export class InferenceClient {
  private worker = new Worker(new URL('../worker/inference-worker.ts', import.meta.url));

  async loadModel(modelPath: string): Promise<void> {
    return new Promise((resolve) => {
      const handler = () => { this.worker.removeEventListener('message', handler); resolve(); };
      this.worker.addEventListener('message', handler);
      this.worker.postMessage({ type: 'load', modelPath });
    });
  }

  async predict(features: number[], stats: { mean: number[]; std: number[] }): Promise<PredictionResult> {
    return new Promise((resolve) => {
      const handler = (event: MessageEvent) => {
        if (event.data.type === 'result') {
          this.worker.removeEventListener('message', handler);
          resolve(event.data.result);
        }
      };
      this.worker.addEventListener('message', handler);
      this.worker.postMessage({ type: 'predict', features, stats });
    });
  }
}
让 Cursor 生成一个完整的 React 组件,在 Worker 中加载 ONNX 模型,通过表单接收用户输入,运行推理,并显示带置信度条的预测结果。这种端到端模式展示了从模型文件到面向用户的 UI 的完整部署工作流。
总结
在 Cursor 中进行机器学习将完整的 ML 生命周期带入一个 AI 驱动的 IDE 编辑器。遵循本指南中的模式——结构化数据预处理、架构良好的 TensorFlow.js 模型、全面的评估指标、ONNX 跨平台部署以及 AI 辅助的流水线生成——你可以比以往更快地将机器学习项目从概念推进到生产。记住仔细管理张量内存,始终使用准确率之外的多个指标进行评估,并让 Cursor 生成你的样板代码,这样你就可以专注于模型架构和数据质量。